ESP32 · 04-agent
Architecture: The Conversational Agent
Note: This document was generated by an AI agent.
Overview
Boto sits on its animated face and listens. Say "Boto" and it starts a conversation; say "Boto, que horas são?" and it handles the request directly. It answers when you stop talking, and its mouth follows its own voice. Then the next sentence needs no wake phrase at all — the conversation remains open.
Nothing in that sentence is done on the ESP32 alone. Speech recognition, language generation and speech synthesis all run on a Mac on the same LAN, over plain HTTP, with no API key and nothing leaving the local network. The device contributes the parts that must be local: noticing that somebody is speaking, deciding when they have stopped, and being the face.
For the source-level protocol, task ownership and service contracts, see the local agent pipeline. The model comparisons below are historical measurements; defaults refer to the tracked example header rather than any particular device.
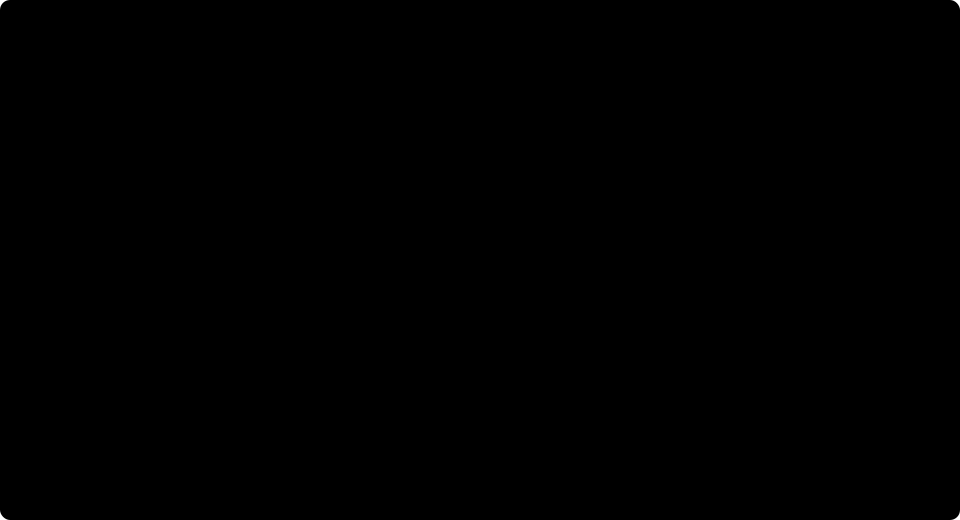
Amber is the device; teal is the Mac. The one dashed box sits in the middle of the round trip but runs on the ESP32.
Two detectors, and why there have to be two
Waking on a phrase is normally one job done by one component: a small neural network that listens to audio and fires on a keyword. This device cannot run that component, so the job is split into three questions, each answered where it is cheapest.
| Question | Kind of question | Answered by | Cost |
|---|---|---|---|
| Is anyone speaking? | Signal | the on-device energy detector | One comparison per 20 ms chunk |
| What did they say? | Language | whisper.cpp on the Mac | 0.5–1.3 s per utterance |
| Was it addressed to me? | Policy | the on-device wake-phrase matcher | A string compare over ≤ 6 tokens |
The split is forced rather than chosen. The device reports a largest contiguous free block of around 61 KB on an ESP32-D0WD-V3 with no PSRAM, and on-device keyword spotting needs far more than that contiguous: Espressif's WakeNet effectively expects an S3 with PSRAM, and microWakeWord's TensorFlow Lite arena alone exceeds the largest free block this board can offer.
The other extreme — streaming continuously to the Mac — was rejected for a different reason: 32 KB/s forever, into a machine already short of memory, for audio that is silence almost all of the time.
So the energy gate is not a weaker wake word. It is a filter that decides what is worth transcribing, and the wake word proper happens afterwards, in text, where it is nearly free. The consequence is stated plainly because it is a privacy property, not an implementation detail: every sustained utterance near the device is transcribed on your machine, not only the ones meant for it. Silence sends nothing, non-wake transcripts never reach the model or the synthesiser, and the wake-word toggle in settings stops listening entirely without a reflash.
Noticing Speech
The unit of time is a chunk, not a millisecond
The capture task hands over 320 samples at a time at 16 kHz, so one push into the detector is exactly 20 ms, and the wake listener computes that from the sample count rather than a clock. That is deliberate — 320 samples is 20 ms whatever the scheduler was doing, while wall-clock timing would fold every scheduling hiccup into the detector's timing. Every duration below is therefore a whole number of chunks:
| Duration | Chunks | What it bounds |
|---|---|---|
| 140 ms | 7 | Before a sound counts as speech |
| 900 ms | 45 | Before an utterance counts as finished |
| 300 ms | 15 | Audio kept from before the trigger |
| 3,000 ms | 150 | One noise-floor measurement |
| 120,000 ms | 6,000 | The watchdog, never the normal path |
Energy with hysteresis
Two thresholds, not one. A single threshold sits exactly where ordinary speech crosses back and forth between syllables, so it chatters — opening and closing several times inside one word. Opening high and closing low gives the detector somewhere to sit.
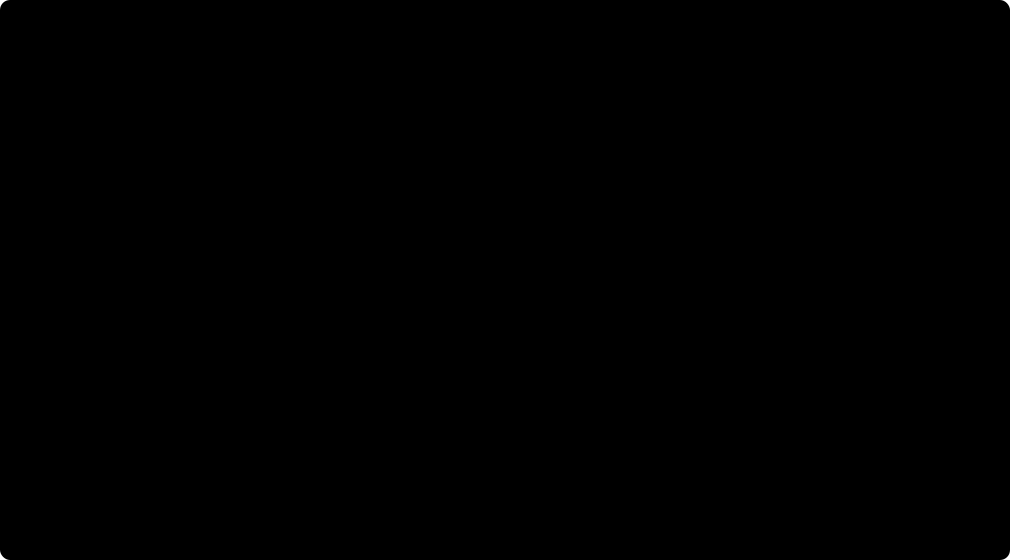
The whole detector, on one word and one question. The second syllable is the case the second threshold exists for.
The candidate rule is the part worth reading twice. One chunk over the opening threshold starts a candidate, and the candidate then survives on the closing threshold.
Without that, the softer second syllable of a two-syllable name resets the 140 ms timer, and the gate opens only on the louder question that follows — losing exactly the word the whole mechanism is looking for. And because a candidate is cancelled rather than paused when the signal falls below the closing threshold, a ticking clock cannot accumulate its way to a trigger over a minute.
When the gate does open, the utterance timer is seeded with the time already spent above the threshold rather than reset to zero, so the watchdog measures from the first syllable and not the second.
The room raises the bar by itself
The configured thresholds are peak magnitudes out of 32,768, applied after the microphone gain setting — change that and these move with it. In the room this was built in, with that gain set to 8, the quiet floor sits at a median of 333 (−39.9 dBFS) and peaks to 1016 (−30.2 dBFS), so an opening threshold of 4000 (−18.3 dBFS) is four times the loudest ambient sample — about 12 dB of margin.
A different room invalidates that margin, so the detector measures the room and lifts the thresholds to clear it:
effectiveOpen  = max(WAKE_OPEN_PEAK,  3 × noiseFloor)
effectiveClose = max(WAKE_CLOSE_PEAK, 2 × noiseFloor)
Three properties of that estimate are load-bearing, and all three are about which statistic gets called "the room".
It is a minimum, not a mean. Speech is loud but intermittent, so an average is dragged upward by every word until the detector can no longer hear anyone. The minimum over a window sees straight past the talker to the fan underneath.
It rises immediately and falls slowly. A window whose minimum exceeds the
current estimate replaces it outright; one below it is mixed in at a quarter
weight, (3·old + new) / 4 per 3 s window. As a time constant that is
τ = −3000 ms / ln(0.75) = 10.4 s (to within 10 % of a drop: 24 s)
A room that genuinely got louder is believed at once; a brief lull cannot drop the bar back onto the noise mid-conversation.
It only ever raises. The adaptation step returns the configured value when adaptation would go below it. The opening threshold is user-tunable, and adaptation that could lower it would silently override a deliberate setting.
The crossover is worth knowing, because it changes the detector's character:
open  adapts once  3 × noise > 4000   →  noise > 1,333   (−27.8 dBFS)
close adapts once  2 × noise > 2000   →  noise > 1,000   (−30.3 dBFS)
Below a noise floor of 1,000 counts, both thresholds are the configured pair and the hysteresis ratio is 2:1. Above 1,333 both adapt and the ratio becomes 3:2 — a narrower gap, so the detector is slightly more prone to chatter in a loud room than in a quiet one. Between those two figures the closing threshold is climbing while the opening one is not, which is the narrowest the gap ever gets. In the room measured above, 3 × 333 = 999, so nothing is lifted at all and the configured numbers are the whole story.
Finally, the estimate is only updated while the gate is closed. During an utterance there is no way to separate the room from the speaker, so the value is frozen — and a stale estimate is the safe one, because it can only be lower than the truth, which keeps the gate easier to open rather than harder.
Opening the turn slightly in the past
Energy detection cannot notice speech until speech has already started. By construction the gate fires the minimum-speech duration after the first crossing, so at least 140 ms of the word is already gone — and on a one-word wake phrase that is precisely the wrong syllable to lose: "oto" will not match "Boto".
The pre-roll buffer keeps a rolling window of the most recent 300 ms:
300 ms × 16,000 Hz = 4,800 samples = 9,600 bytes, in .bss
Twice the 140 ms detection delay, with the remainder covering the onset that was below the threshold and therefore never seen at all.
Unlike the standard ring buffer, it is meant to lose data. A full ring buffer refuses the write; this one discards its oldest samples, because the oldest are the ones that stopped mattering. It is also single-threaded by design — both the writing and the draining happen on the capture task — so none of the ring buffer's producer/consumer care is needed.
Its 9,600 bytes are static on purpose. A static buffer lowers the heap ceiling once, at link time, and can never fragment what remains; the same bytes taken from the heap could. That is not a hypothetical: adding this buffer moved the largest contiguous free block from about 61 KB to about 53 KB, which is what broke the browser recorder's buffer and forced its third and final cut. The full accounting is in the contiguous-heap ledger.
A decorator, not a second consumer
The audio capture entry point deliberately allows exactly one consumer, and that single choke point is worth keeping. So the listener wraps the real agent rather than competing with it: closed, it buffers into the pre-roll and forwards nothing; once a turn opens it flushes the pre-roll and then forwards live audio.
One ordering detail is load-bearing. The pre-roll is flushed on the first forwarded chunk, not when forwarding begins, because starting a turn on the local agent clears its uplink ring — anything pushed before that would be thrown away with it.
The listener also has to yield. It holds the microphone whenever the device is idle, so without help the browser's monitor and recorder would be refused for as long as the feature was switched on. The capture entry point adds one exception to the one-consumer rule: the browser's monitor and recorder can displace the listener as preemptable consumers, and the main controller's per-frame reconcile re-arms the listener when they finish — neither side calling the other.
Tuning is passed in on every listen call rather than read from the static configuration, which is what keeps this component host-testable, and it is also what lets the runtime slider work. The wake-reconciliation step scales both thresholds together, deriving the closing threshold from the opening one rather than storing them independently.
So the compile-time pair sets the ratio, currently 1:2, and moving the opening-threshold slider in the web UI moves the closing threshold with it. Without that the hysteresis would collapse at one end of the slider and invert at the other — and the detector's setup step clamps an inverted pair anyway, because a detector that closes before it opens is worse than a badly tuned one.
Deciding Whether It Was Addressed
The wake-phrase matcher answers two questions, and which one applies depends on whether a conversation is already open.
Cold: the name must come first
An accepted spelling of Boto must be the first token. "Boto" alone is an invitation to start talking; the agent supplies "Vamos conversar" to the model so the reply asks for a topic instead of free-associating from one word. These mentions later in a sentence stay silent:
"Eu boto a mesa depois do almoço." "O boto cor-de-rosa vive na Amazônia." "Ontem eu vi um boto e falei com ele." — mentioned, not addressed
Matching is fuzzy because Whisper hears a name it does not know and spells it however it likes — Boto, Botto, Bote, Voto — and punctuates freely. A configured list holds the accepted spellings; keep it narrow if false wakes become common, since any of them at the start of room speech will wake the device.
A token is a run of letters, digits, or any byte with the high bit set, so a UTF-8 sequence never splits a word; everything else separates. Tokens are folded through an ASCII-folding step per token, into a scratch buffer, for comparison only, so case and accents do not affect matching while the returned offset still points into the original string. Folding the whole transcript first would shift that offset, and the offset is what lets the model be prompted with the question rather than the greeting.
Warm: is the follow-up meaningful?
Nobody says "Boto" before every sentence, so once Boto has answered, the phrase is not required for a while. Something still has to stand between the model and an open microphone.
An always-on mic pointed at a room produces a great deal of nothing — and Whisper does not return nothing. It returns its best guess at nothing:
[Música]        (música de fundo)        [BLANK_AUDIO]
Legendas pela comunidade Amara.org
Those are what close a conversation rather than continue one. The filter is
three cheap tests over at most six tokens: fewer than two tokens is a cough, not
a question; a transcript that opens with [ or ( is a marker; and any token
matching the known credit-line hallucinations (legendas, amara, subscribe,
inscreva, …) rejects the whole thing.
Deliberately strict, and asymmetrically so: a follow-up wrongly ignored costs one repeat, while a follow-up invented from room noise makes the device answer the furniture.
The conversation window
| Event | Effect |
|---|---|
| A turn is answered | Window opens (or extends) for 20 s, measured from when the reply finishes playing |
| An utterance arrives with nothing in it | Window closes; the phrase is required again |
| A tap | Window closes, along with the turn |
Timing it from the end of the reply rather than the start of the turn matters — otherwise the device would spend its own window talking, and a long answer could consume all of it before anyone had a chance to follow up.
The window also owns a bounded semantic history. Up to four completed user/Boto exchanges are included with the next accepted follow-up, so pronouns, short answers and references to the previous reply retain context. A cold wake phrase or a touch-started turn clears that history and begins a new conversation.
While the window is open the face holds the listening pose. A microphone that is going to act on the next thing you say must not look identical to one that is not, and on a device with one screen and no lights, that is the only channel available to say so.
The Turn Itself
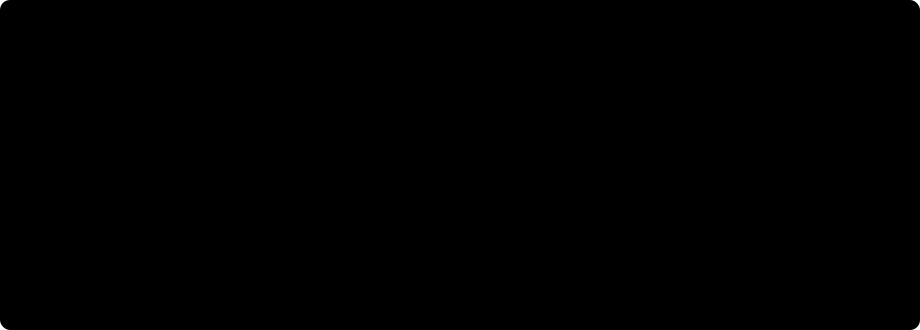
Measured on this hardware. The model load is the term that moves.
The second bar is the one this document is responsible for. The silence timeout is paid on every single turn — it is the floor under the device's response time, and no amount of work elsewhere in the pipeline can recover it. Shortening it would make the device feel faster and cut sentences in half at the first pause for breath; 900 ms sits above ordinary disfluency pauses and below the point where the wait becomes noticeable.
The maximum-utterance watchdog is not a second limit of the same kind. At 120,000 ms it is a watchdog: silence is what normally ends a turn, and the chunked upload places no cap on how long somebody may speak. Two minutes of continuous speech means something is wrong — background voices the adaptive floor cannot separate from a person — and firing is the recovery. It must stay at or below the transcription service's own utterance ceiling, and it must never be set to zero, which the detector reads as "no ceiling" and is the one value that can hang a turn forever.
One state machine, two ways in
The hands-free path is not a second turn driver. It is two more ways to produce the same two events.
The voice-turn state machine is the same state machine the touch pad drives, and the hands-free path reuses it entirely — it only changes what starts and ends a turn. Two integration rules earned their comments the hard way:
The turn driver must know every way a turn can start. The turn-driving update step originally gated on "are we on a voice tab", which silently abandoned any turn begun another way. That bug appeared twice: once when the Speak tab gained a long-press, and once when the wake word arrived.
A reconcile must not fight the turn it is serving. The wake-reconciliation step, gating on whether the session was idle alone, took the microphone away one frame after each turn opened — before the pre-roll had even been flushed — so the transcriber received six seconds of silence. It read as "the wake word does nothing" while every counter insisted a turn had run. The rule the file now states: anything that can stop a turn has to know how that turn was started.
Two further conditions gate arming at all. The listener stays disarmed while the amplifier is live, plus a 900 ms cooldown afterwards — without that, Boto hears itself say its own name and the loop does not end. And it will not arm before the network is up, because a turn with nowhere to send its audio is exactly what happened on this feature's first boot, when a transient on the settling microphone opened a turn that then failed to reach the transcriber.
The face through a turn
| State | Face |
|---|---|
| Conversation open, idle | Listening pose |
| Listening | the listening cue |
| Thinking | the thinking cue |
| Speaking | Mouth follows the audio amplitude |
| Done | Success cue, then back to the pose |
One subtlety: the Speaking state is entered on the model's first token, but nothing is audible until Piper has synthesised the first sentence — a gap of a second or two. The mouth is handed to the audio at the first token anyway, because the playback-level reading is zero until there is something to hear, and that draws exactly the shut mouth the gap calls for. Letting the canned talking expression's wobble fill it instead made the character mime talking to silence and then snap into sync.
How the mouth follows the audio at all is the subject of making the agent audible.
Acting, Not Only Answering
With both device commands and model-routed commands enabled — both on by
default in the tracked configuration — the model is asked for a structured
object instead of prose, and the board sends its own capability catalogue with
every request so a disabled panel is never offered. That catalogue is not free:
it costs about 640 extra prompt tokens per cloud turn, measured on this
device's real catalogue, where a 65-token prompt becomes roughly 706. The usage
panel shows it immediately. Turning model-routed commands off falls back to
exact-phrase matching, where allowlisted commands still run locally and
everything else is ordinary conversation. See
structured device actions for
the {kind,operation,target,phrase} contract, its validation, and the action
lifecycle. (An earlier iteration asked for a smaller {cmd,phrase} envelope over
a streamed reply; that wire format is gone, but the reasoning below — that
structured output has a real cost for a small model — still held when the newer,
larger format was measured.)
The ESP32 owns what each operation does; the model only gets to name one from a catalogue built from what the device actually has enabled, and an unrecognised or disabled target resolves to nothing — so a model that guesses badly produces a rejection rather than a surprising action. An explicit JSON schema request — not just asking for JSON as text — is what makes this dependable: constraining the shape at the API level, rather than hoping the model's prose happens to parse, is what turned "usually valid" into "always well-formed or explicitly rejected."
When the animation actually plays
The dispatcher acknowledges an animation request, then waits for that acknowledgment to finish speaking before actually starting the scene — reserving its playback duration before returning to the listening cue. See the lifecycle for the full state machine.
Classic style has only a subset of scenes available as expressions; a target outside that subset is rejected for that style rather than silently no-op'd.
This needs a model bigger than 1B
The mechanism is reliable. The model's judgment is what is not, and the cost falls on the wrong thing — measured on the same six questions:
llama3.2:1b | phi4-mini | |
|---|---|---|
| Command correct | ~3/6 | 5/6 |
| "Quanto é 17 vezes 23?" | "O Boto estou feliz!" | "Isso não posso calcular diretamente" |
| "Meu cachorro morreu" | "Desculpe, tiveram um perda" | "Sinto muito, isso é muito difícil" |
The second row is the one that matters. Asked the same arithmetic as plain
prose, llama3.2:1b answers "17 x 23 = 391" correctly — it is the envelope
that breaks it. A 1B model spends its capacity on the JSON and the command
selection, and the reply pays for it.
Rewording the prompt made it worse (everything collapsed to happy).
Temperature 0 made it consistent and worse. A separate classification call scored
1 of 6. The conclusion is the model, not the plumbing.
Those measurements are why the flag is separable rather than implied by the device-commands setting, and the choice now depends on which provider answers:
- A cloud provider, or
phi4-mini— both settings on, which is the tracked default. The catalogue's token cost is the price, and it is visible llama3.2:1b— model-routed commands turned off. Exact local actions plus natural chat; leaving it on trades worse answers for broader command phrasing, which is the wrong trade on a 1B model
Choosing the Models
The Mac has 8 GB, shared between three services. That forces a choice, and the choice is not the obvious one.
Transcription wins. A mangled question does not produce a worse answer — it produces a confident answer to a question nobody asked, which is harder to notice and harder to debug than silence.
ggml-base was measured against clean, synthesised Portuguese, so the microphone
could be ruled out entirely:
| Spoken | ggml-base heard |
|---|---|
| "Olá Boto, que horas são?" | "Há um botão que é hora de sal." |
| "Me conta uma piada curta por favor" | "Me conto uma piada, cuuta por favor." |
That also explained the wake word appearing to fail: "Há um botão" does not start with an accepted spelling of Boto, so the matcher correctly declined to answer — a rejection that was right about the text it was given and useless to the person in the room.
ggml-small transcribes the same recording exactly right in 0.5–1.3 s,
against base's 1.6 s — faster, because base was spending its time decoding
nonsense. The first inference after a server start takes 4.6 s, which is why the
transcription reply timeout is generous.
The memory that buys comes back out of the language model: llama3.2:1b stays
resident and generates at 40 tok/s, where phi4-mini loads in 12.6 s, gets
evicted between turns, and manages 16–17 tok/s.
A configured decoding-bias prompt costs nothing and helps measurably. Whisper treats it as the words immediately preceding the audio, biasing decoding toward that vocabulary — on one recording it turned "que hora salva" into "que horas são" and "previsal do tempo" into "previsão do tempo".
Diagnosing It
Serial output has never been readable in this setup, so the device reports on itself over HTTP, through a diagnostic status endpoint:
That status includes what was last heard, the current capability catalogue and its length, how many turns ran and were accepted or rejected, whether transcription failed and why, the last spoken reply, how much conversation memory is retained, and the live wake-word settings.
What was heard is kept whatever happened to it afterwards — deliberately separate from the transcript the wake gate clears on a rejection, because "it heard you and decided you weren't talking to it" and "it heard nothing at all" are completely different faults that look identical without it. The capability catalogue is reported for the same reason: an empty tool catalogue looks exactly like a model that chose not to act.
One thing this endpoint does not report is the threshold actually in use. The detector computes its effective opening threshold, closing threshold, and noise floor internally, and exposes them precisely so a caller can say what the detector is really listening for, but the status endpoint currently returns only the configured opening threshold. In a room quiet enough that nothing is lifted — the room these defaults were measured in — the two agree. In a louder one they do not, and the table below reads the configured threshold as the lever when the real one is three times the noise floor.
| Symptom | Cause | Fix |
|---|---|---|
| Turn count stays 0 | Never crossed the threshold | Lower the opening threshold — but see the note above if the room is loud |
| Turn count rises, nothing heard | Triggering on noise | Raise the opening threshold |
| It heard the question but lost "Boto" | The name never began a speech candidate | Lower the opening threshold until the first syllable crosses it |
| It heard words, but wake rejections rise | Phrase not matched | Add the spelling to the accepted-spellings list |
| Follow-ups ignored inside the window | The meaningfulness check rejected it: under two words, or a credit-line hallucination | Say more than two words |
| Device answers itself | Cooldown too short for the room's reverberation | Raise the cooldown duration |
| A turn never ends | The maximum-utterance watchdog set to 0, which the detector reads as no ceiling | Restore a non-zero value |
| Transcription error: connect refused | Transcriber not running | Start the transcription server |
| Transcription error: no reply before timeout | Running but slow | Raise the transcription reply timeout |
| Transcription error: server refused the request | Malformed request | Check the multipart build |
| Transcription error: request too long to build | The decoding-bias prompt overflows its buffer | Shorten it |
The transcription error field is reset immediately before each Whisper attempt, not once at turn start, so a text-only turn (which never touches Whisper at all) cannot blank it — the value read here always describes the most recent real attempt, never a stale one from turns ago. And a connection-refused failure is no longer a purely silent failure: with the network otherwise up, the device speaks a short phrase ("Não consegui te ouvir agora.") instead of just entering the error cue with nothing said — see failing audibly, not silently.
That endpoint is how a real bug was found: adding the decoding-bias prompt left
the multipart epilogue buffer 26 bytes short, truncating the closing boundary so
every request became a 400. The subtler half is worth remembering —
snprintf returns the length it wanted to write, so the Content-Length
described bytes that were never sent. A bounds-checked formatting helper now
returns 0 on truncation and the upload refuses to send rather than building a
malformed request.
Configuration
| Setting | Default | Effect |
|---|---|---|
| Wake listener enabled | Off | Tracked template default; turned on to compile listener integration |
| Accepted wake-word spellings | configured list | Accepted Whisper spellings of the one-word trigger |
| Opening peak threshold | 4000 | −18.3 dBFS; 4× the loudest ambient sample measured here |
| Closing peak threshold | 2000 | −24.3 dBFS; with the above, a 2:1 hysteresis ratio |
| Minimum speech duration | 140 ms | 7 chunks of sustained sound before it counts |
| Silence duration | 900 ms | 45 chunks; paid on the latency of every turn |
| Maximum utterance duration | 120,000 ms | Watchdog, not a speaking limit. Never zero |
| Cooldown after speaking | 900 ms | Deafness after the speaker stops |
| Pre-roll duration | 300 ms | 4,800 samples, 9,600 bytes of static memory |
| Follow-up window | 20,000 ms | How long a conversation stays open after the reply ends |
| Conversation history turns | 4 | Completed exchanges retained during that window |
| Model-routed commands enabled | On | Model-routed actions; ~640 extra prompt tokens per turn. Off for exact phrases only |
| Decoding-bias prompt | phrase + examples | Decoding bias |
| Wake word / wake sensitivity | runtime setting | Runtime equivalents, from the web UI |
The detector's own constants — the 3 s noise window, and the 3× and 2× multiples over the measured floor — are not configurable. They are properties of the detector rather than of the room.
See Also
- Making the agent audible — the compressor, and the mouth that follows the reply
- Audio diagnostics — the heap ledger the pre-roll appears in
- I2S audio runtime — the capture and playback tasks
- Runtime — controller modes and character cues